

C++ inference for supported Qwen models and TurboQuant GGUF weights on NVIDIA GPUs (CUDA) and Apple Silicon (Metal), with an OpenAI-compatible HTTP server.
Quick start | Documentation | Benchmarks | Credits
New in 1.4.4 (same machine, same session for every comparison):
- DGX Spark, Qwen3.8-27B: prompts up to 1.42x faster than TensorFold 1.2.3 in its own record setup (8 slots x 131,072), faster at every length from 2K to 128K, also on TensorFold's own EXL3 file.
- RTX 3090, Qwen3.8-Flash-Next (125B MoE, 6B active): with 2 to 12 users at once, up to 34 % more total output than Strata 0.2.12; no more out-of-memory on long answers on 24 GB cards.
- Mac, Qwen3.8-27B 4-bit (48 GB M5 Pro): answers 8-44 % faster than Splash 1.5.0 from 16K to 128K, and a 256K context
where TensorFold does not fit. Install with
brew install turbo-tan/tap/tqllm. - New files: Unsloth Dynamic v3.1 Flash-Next GGUFs, NVIDIA's NVFP4 Flash-Next experts, Qwen3.8-27B EXL3 folders.
Flash-Next setup (RTX 30 or newer with 24 GB and 64 GB RAM, or a GB10): YTan2000/Qwen3.8-Flash-Next-tqLLM. Benchmarks.
Checked on the release build: the model loads and answers a fixed question correctly (1.4.4: RTX 3090, M5 Pro Mac).
| Model | Files tqLLM loads | Hardware | 1.4.4 check |
|---|---|---|---|
| Qwen3.8-27B and fine-tunes (e.g. Qwopus3.8) | TQ3_4S, TQ_L / TQ4, K-quant and IQ GGUFs; EXL3 folders; DFlash2 and MTP drafters | NVIDIA, 16 GB and up; DGX Spark / GB10 | passed |
| Qwen3.8-27B on a Mac | mlx-community 4-bit, TQ_L, QSA files (Mac guide) | Apple Silicon (48 GB tested) | passed |
| Qwen3.8-Flash-Next (125B MoE, 6B active) | .tqfn manifest over the public IQ3_S GGUF, tqLLM's own file, Unsloth Dynamic v3.1 GGUFs, NVIDIA NVFP4 experts |
24 GB GPU + 64 GB RAM; DGX Spark / GB10 | passed |
| Qwen3.5 / Qwen3.6 27B | same formats as Qwen3.8-27B (same architecture) | NVIDIA | not re-run for 1.4.4 |
| GLM-5.3-Flash, MiniMax-M3.1-Flash | GSQ GGUF; EXL3 folder (guide) | one GB10, one request | not re-run for 1.4.4 |
Not supported yet: Qwen3.5 sizes with tied embeddings (4B and smaller: the file has no output.weight), and
Qwen3.5 / 3.6 mixture-of-experts GGUFs (qwen35moe, such as Qwen3.6-35B-A3B) are not verified on 1.4.4.
Watch prefill, output rates and hardware use in one view. Both rates stay in the
same request card. Open http://localhost:8086/ or /monitor on the API port.
No frontend build, extra service or second port is required.

Watch the 50-second monitor walkthrough
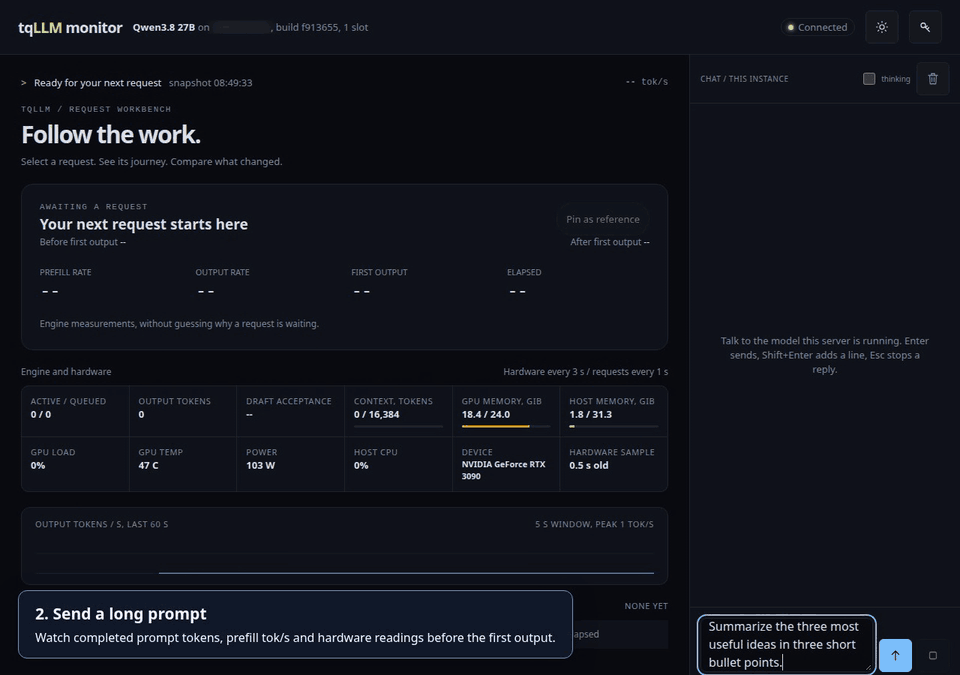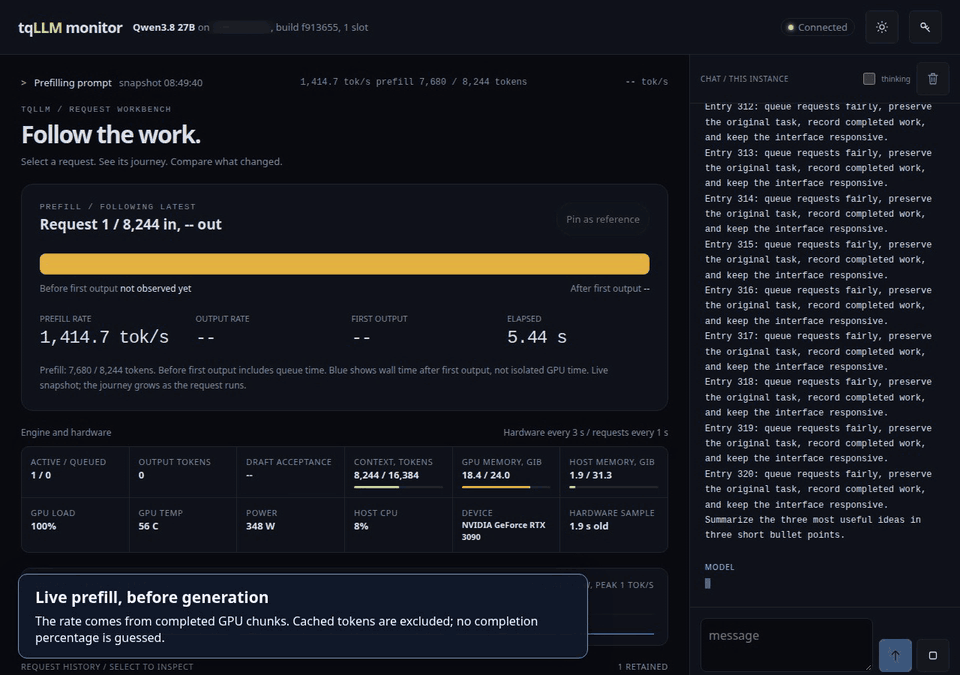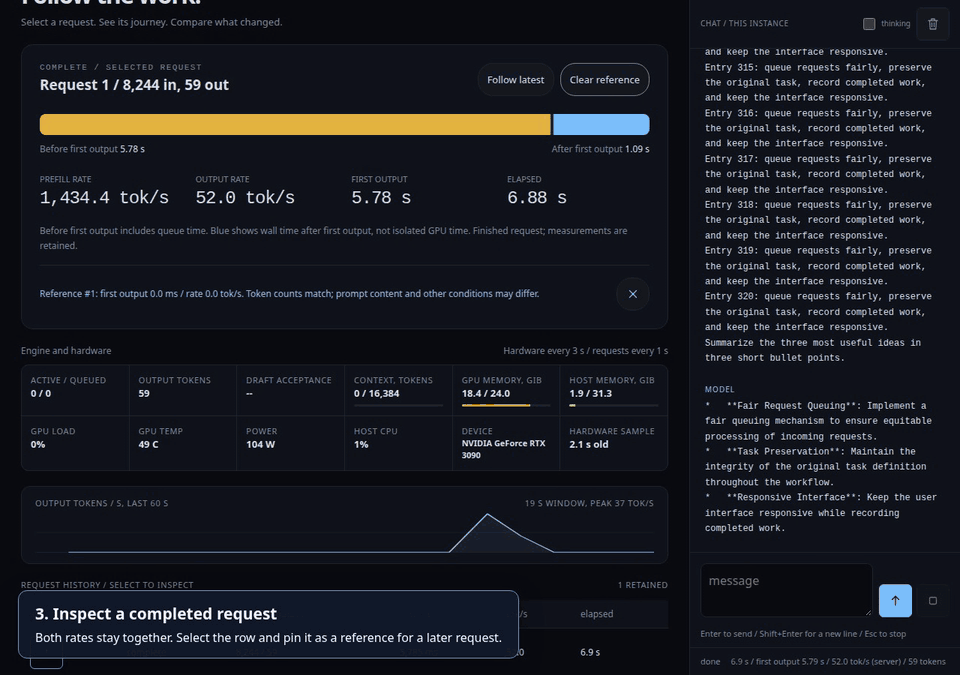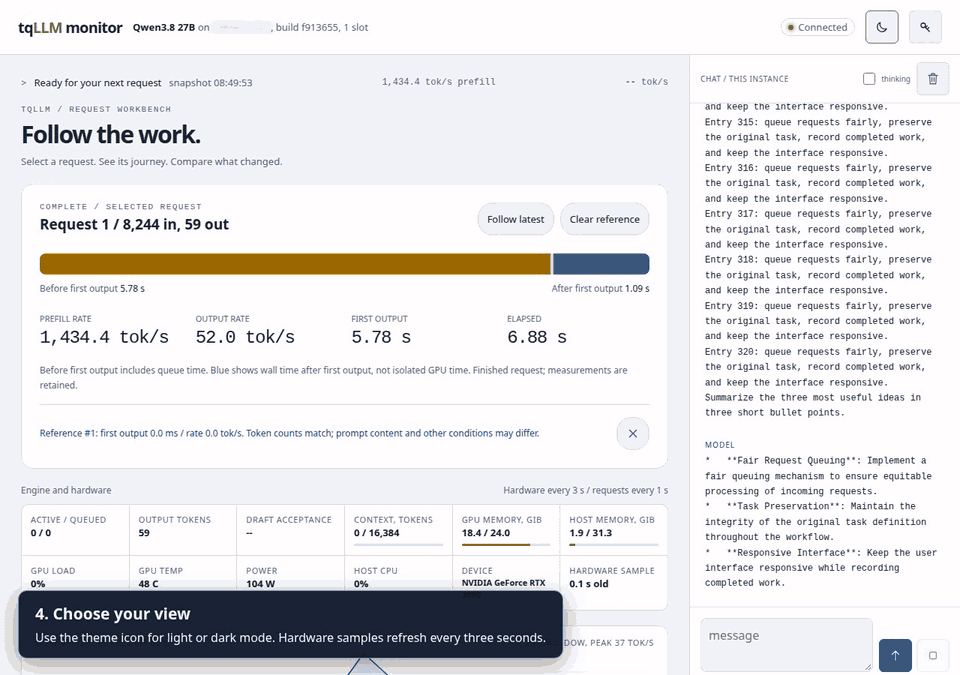
20-second preview above; full video and step-by-step instructions. Recorded with a real model. The local hostname is hidden; telemetry is unmodified.
On a Mac (Apple Silicon, macOS 15 or newer):
curl -fsSL https://tqllm.com/install.sh | bash   # or: brew install turbo-tan/tap/tqllm
tqllm serve                          # first run downloads the model and drafter
tqllm claude                         # Claude Code pointed at the local server (or: tqllm codex)
More in the Mac guide. The steps below are for Linux with an NVIDIA GPU. Place a supported Qwen GGUF at
models/model.gguf, then build from source:
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release -DCMAKE_CUDA_ARCHITECTURES=native
cmake --build build --target tqserve -j4
./build/tqserve --model models/model.gguf --port 8086
Open localhost:8086 for the monitor. Applications use
the same server at http://localhost:8086/v1.
Prefer Docker? The prebuilt image (x86-64 and arm64) runs the same server:
docker run --rm --gpus all -p 127.0.0.1:8086:8086 -v "$PWD/models:/models:ro" --entrypoint tqserve \
  ghcr.io/turbo-tan/tqllm:1.4.4 --model /models/model.gguf --host 0.0.0.0 --port 8086
or build it locally with docker compose up --build. See installation and requirements.
| You want to... | Read |
|---|---|
| Run on a Mac (Apple Silicon, Metal) | Mac |
| Download a model and add a drafter | DFlash2 and MTP |
| Run MiniMax-M3.1-Flash or GLM-5.3-Flash on a DGX Spark / GB10 | Big MoE models on one GB10 |
| Run on an RTX 5090 (numbers, what is automatic) | RTX 5090 |
| Use a local coding agent | Agent setup |
| Serve several users or tune memory | Server options |
| Run a longer context | TqCache |
| Understand TQ3, TQ4 and compatible formats | Weight formats |
| Inspect latency, compare requests and extend the dashboard | Monitor guide |
See CONTRIBUTING.md for building, testing and contribution requirements, and the architecture guide for the source map.
Built on work from Qwen, ggml/llama.cpp, Google Research, z-lab, Tom Turney, spiritbuun, turboderp (ExLlamaV3: the trellis format and kernels behind X3 and our EXL3 support) and the contributors listed in Credits. Third-party notices remain in NOTICE. Thank you to our community testers.
tqLLM is created by David Y. Tan and licensed under Apache-2.0: if you copy or redistribute it, keep the NOTICE file's credit with your copy. Model weights and third-party components retain their own licences.