A Multilingual, Multimodal Translation Model Family
Multimodal Translation (Vision & Audio), Controlled Dubbing, and Long-Document Translation
🌐 Demo ·
⚡ Free API ·
🤗 Hugging Face ·
 ModelScope ·
📚 Report ·
🤗 Papers ·
🤗 Benchmarks ·
🐧 QQ
Important
New: Index-Translate-Omni 2B / 9B / 35BA3B brings together text translation, image translation, Chinese/English speech recognition, and bidirectional Chinese–English speech-to-text translation. Downloads and benchmarks.
| Model | Hugging Face | ModelScope | Release status |
|---|---|---|---|
| Index-Translate-Omni 2B | 2B | 2B | Available |
| Index-Translate-Omni 9B | 9B | 9B | Available |
| Index-Translate-Omni 35BA3B | 35BA3B | 35BA3B | Available |
The checkpoints use the native package layout. Follow the native inference guide and each model card.
| Model | FLORES COMET22 ↑ | WMT24++ COMET22 ↑ | WMT26 Judge ↑ | MEME ↑ |
|---|---|---|---|---|
| Index-Translate 2B | 0.8655 | 0.8489 | 60.26 | 0.6443 |
| Index-Translate-Omni 2B | 0.8655 | 0.8489 | 60.26 | 0.6443 |
| Index-Translate 9B | 0.8789 | 0.8601 | 75.35 | 0.7387 |
| Index-Translate-Omni 9B | 0.8789 | 0.8601 | 75.35 | 0.7387 |
| Index-Translate 35BA3B (preview) | 0.8794 | 0.8586 | 76.76 | 0.7405 |
| Index-Translate-Omni 35BA3B | 0.8795 | 0.8593 | 78.01 | 0.7405 |
| Model | instTrans Quality / IFscore ↑ | instTrans_minor Quality / IFscore ↑ / Off-target ↓ | IFMTBench XCOMET-XXL / IFscore ↑ |
|---|---|---|---|
| Index-Translate 2B | 0.5391 / 0.7569 | 0.3050 / 0.6586 / 3.97% | 0.7712 / 0.7584 |
| Index-Translate-Omni 2B | 0.5391 / 0.7569 | 0.3050 / 0.6586 / 3.97% | 0.7712 / 0.7584 |
| Index-Translate 9B | 0.6771 / 0.8209 | 0.5222 / 0.7725 / 3.47% | 0.7957 / 0.8760 |
| Index-Translate-Omni 9B | 0.6771 / 0.8209 | 0.5222 / 0.7725 / 3.47% | 0.7957 / 0.8760 |
| Index-Translate 35BA3B (preview) | 0.6901 / 0.8336 | 0.5151 / 0.7715 / 4.05% | 0.7926 / 0.8991 |
| Index-Translate-Omni 35BA3B | 0.6867 / 0.8371 | 0.5163 / 0.7843 / 3.62% | 0.7934 / 0.9070 |
Original Index-Translate figures come from the published benchmarks. The original 35BA3B reference is the published preview checkpoint.
CER is a percentage (lower is better). BLEU and chrF2 are higher-is-better. Translation cells show BLEU / chrF2 / target CER.
| Model | Chinese ASR CER ↓ | English ASR CER ↓ | English → Chinese | Chinese → English |
|---|---|---|---|---|
| Index-Translate-Omni 2B | 13.8113 | 34.2560 | 36.982 / 30.357 / 43.3452 | 30.747 / 51.152 / 48.0670 |
| Index-Translate-Omni 9B | 17.8917 | 14.4097 | 43.507 / 36.312 / 41.3767 | 34.656 / 55.376 / 46.3720 |
| Index-Translate-Omni 35BA3B | 13.0053 | 15.4950 | 40.074 / 32.862 / 44.8097 | 32.411 / 53.452 / 46.1700 |
35BA3B uses one shared audio encoder and connector for all four tasks, with repetition penalty 1.1 for English ASR and the original decoding for the other tasks. Results use the same 30 fixed samples per task. One English → Chinese case reached the 256-token limit with no target translation and remains in the score. Sample counts differ across model sizes.
COMET22 × 100 (higher is better). Each Omni model is compared with its Qwen3.5 baseline on paired evaluated subsets.
| Model | MMTIT ↑ | FLORES-rendered ↑ | Vistra ↑ |
|---|---|---|---|
| Qwen3.5-2B | 52.164 | 50.187 | 55.326 |
| Index-Translate-Omni 2B | 65.809 | 53.612 | 65.596 |
| Qwen3.5-9B | 73.814 | 67.804 | 68.963 |
| Index-Translate-Omni 9B | 77.604 | 68.438 | 71.815 |
| Qwen3.5-35B-A3B | 75.602 | 70.005 | 71.067 |
| Index-Translate-Omni 35BA3B | 77.011 | 69.891 | 71.482 |
35BA3B reuses the verified image scores for the same weights. Results cover the evaluated subsets; the original failure and UNKNOWN scoring rules are retained.
Tip
🚀 Free Public API Now Available! Call Index-Translate-35B-A3B directly with zero GPU setup. Fully OpenAI-compatible at https://index-translate.bilibili.com/v1. Try it in seconds with python inference/llm/call_api.py "Hello, world!" --target zh! 👉 API Quick Start
Index-Translate is a family of multilingual, multimodal translation models built on Qwen3.5. The text models cover 150 languages and follow translation instructions such as terminology, formatting, and content-preservation requirements. The family extends this unified multilingual foundation to multimodal translation (visual images and audio speech), syllable-controlled translation, and full-document translation.
- Index-Translate (Text & Multimodal Vision): Covers 150 languages for text translation, with native support for multimodal image translation (native vision encoder, zero OCR dependency), structured content, hard/soft instruction following, and community expressions.
- Index-Echo (Multimodal Audio & Speech): End-to-end speech-to-subtitles (S2TT) and cross-lingual voice-cloned dubbing (S2ST), preserving the source speaker's voice characteristics while translating.
- Index-Homura (Controlled Dubbing): Dynamically adjusts translations to match a specified target syllable budget for syllable-level timing alignment.
- Index-NativeLong (Long Document): Supports long-context input for complete documents, maintaining term and character name consistency across paragraphs.

The radar includes 35B-A3B (preview), 9B, and 2B, with fixed per-axis min–max ranges across all 14 models. Its seven axes are WMT, FLORES, instruction following, low-resource translation, subtitles, MEME, and books/fiction. Instruction following averages instTrans and IFMTBench IFscore. The normalized scale is not an accuracy percentage. The gray dashed line combines the best non-Index score on each axis and does not represent one model. Raw category scores · Figure notes · Individual benchmark results.
Omni · News · ⚡ Free API · ✨ Multimodal Translation · Models · Quick start · Instruction Following · Examples · Evaluation · Benchmarks · Applications · TODO · Papers and citation
- 2026-11-05: introduced Index-Translate-Omni 2B / 9B / 35BA3B for text/image translation, Chinese/English ASR, and bidirectional Chinese–English speech translation. See the pinned downloads, release status, and benchmarks.
- 2026-10-10: launched official Multimodal Image Translation support! The full family (Index-Translate 2B / 9B / 35B-A3B) natively supports end-to-end image translation. The free public API, Web Demo, Python script (call_api.py), and GGUF
mmprojweights all support image input with zero external OCR dependencies. See the Tutorial Guide. - 2026-10-04: released free public API endpoints on index-translate.bilibili.com/v1 for Index-Translate-35B-A3B. Fully OpenAI-compatible. Try it with call_api.py.
- 2026-10-04: released four Index-Translate benchmarks, with datasets/metadata on Hugging Face and evaluation scripts and guides on GitHub.
- 2026-10-03: released official quantized builds across the family on Hugging Face and ModelScope — GGUF for llama.cpp local inference (including visual
mmprojweights), alongside FP8 (W8A8) and NVFP4 (W4A4, Blackwell-optimized) for vLLM serving. - 2026-09-30: released Index-Translate, with 2B / 9B / 35B-A3B (preview) text-model weights on Hugging Face and ModelScope, the technical report, and the online demo.
- Release official quantized builds (GGUF for llama.cpp local inference, FP8 and NVFP4 for vLLM serving) for the whole family.
- Release instTrans, MEME, SandGlass and NAtIveLong data/metadata and evaluation code; see Benchmarks.
- Release Index-Translate-Omni with text and image translation, Chinese and English ASR, and bidirectional Chinese–English speech-to-text translation.
- Add native video and long-document translation to Index-Translate-Omni.
- Index-Echo-S2ST: add support for more languages.
- Scaling out (100B+).
The links below include the Omni native packages and the original 2B, 9B, and 35B-A3B (preview) text-model checkpoints. Evaluation results are included in the comparison tables.
| Category | Model | Task and released package coverage | Hugging Face | ModelScope | Inference Guide |
|---|---|---|---|---|---|
| Text, Vision & Speech | Index-Translate-Omni | Text/image translation, Chinese/English ASR, and Chinese ↔ English speech translation | 2B · 9B · 35BA3B | 2B · 9B · 35BA3B | Release status and native guide |
| Text & Multimodal Vision | Index-Translate | Text & multimodal image translation across 150 languages, instruction following | 2B · 9B · 35B-A3B (preview) (⚡Free API) | 2B · 9B · 35B-A3B (preview) | Guide · Free API · Image Guide |
| Multimodal Audio & Speech | Index-Echo S2TT | Speech → subtitles; packaged script: zh→en/ja/es | 2B · 9B | 2B · 9B | Guide |
| Multimodal Audio & Speech | Index-Echo S2ST | Speech → speech; zh→en/es/ja, en→zh/es/ja (voice cloning) | 2B · 9B | 2B · 9B | Guide |
| Controlled Dubbing | Index-Homura | Translation with a target syllable count | 2B · 9B | 2B · 9B | Guide |
| Long Document | Index-NativeLong | Long documents; fixed templates: zh↔en, zh↔ja | 2B · 9B | 2B · 9B | Guide |
Naming: Index-NativeLong is published under the model IDs IndexTeam/Index-Nailong-2B and IndexTeam/Index-Nailong-9B. Use those IDs in commands. Language support for the speech and long-document packages is listed separately from the text models' 150-language coverage.
Quantized builds: the original Index-Translate, Index-Homura, Index-NativeLong, and Index-Echo families below are also published in GGUF (llama.cpp local inference; all bit-widths in one repository per model, vision mmproj included where applicable), FP8 (compressed-tensors W8A8, ready for vLLM serving), and FP4 (compressed-tensors NVFP4 W4A4, for Blackwell GPUs). For the Index-Echo speech models, the GGUF repositories contain the text LLM backbone only, while the FP8/FP4 repositories ship the complete pipeline with a quantized LLM. All repositories are mirrored on ModelScope.
| Model | GGUF (llama.cpp) | FP8 (vLLM) | FP4 (vLLM, Blackwell) |
|---|---|---|---|
| Index-Translate | 2B · 9B · 35B-A3B (preview) | 2B · 9B · 35B-A3B (preview) | 2B · 9B · 35B-A3B (preview) |
| Index-Homura | 2B · 9B | 2B · 9B | 2B · 9B |
| Index-NativeLong | 2B · 9B | 2B · 9B | 2B · 9B |
| Index-Echo S2TT | 2B · 9B (LLM backbone) | 2B · 9B (full pipeline) | 2B · 9B (full pipeline) |
| Index-Echo S2ST | 2B · 9B (LLM backbone) | 2B · 9B (full pipeline) | 2B · 9B (full pipeline) |
You can call our free online API directly without local GPUs. We recommend using our zero-dependency Python script inference/llm/call_api.py:
# 1. Quick command-line translation (zero dependencies, works out-of-the-box)
python inference/llm/call_api.py "你好,世界。今天天气不错,我们去公园散步吧。" --target en

# 2. Multimodal image translation (all sizes 2B / 9B / 35B natively supported, zero OCR dependency)
python inference/llm/call_api.py --image path/to/screenshot.png --target zh               # Default 35B flagship
python inference/llm/call_api.py --image photo.jpg --target zh -m Index-Translate-2B    # 2B edge lightweight
python inference/llm/call_api.py --image diagram.png --target en -m Index-Translate-9B   # 9B workstation balanced

# 3. Local proxy bridge for browser extensions (e.g. Immersive Translate / 沉浸式翻译)
# Browser extensions require a local bridge proxy due to CORS/WAF headers and thinking tag suppression:
python inference/llm/call_api.py --serve
# Then configure Immersive Translate:
# - Service: Custom / OpenAI
# - API URL: http://127.0.0.1:8080/v1
# - Model: Index-Translate-35B-A3B
# - API Key: Any string (e.g. index)

# Option A: Standard Chat Completions API (OpenAI-compatible)
curl https://index-translate.bilibili.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Index-Translate-35B-A3B",
    "messages": [{"role": "user", "content": "请将以下文本翻译为英语,直接输出翻译结果,不要进行任何解释。\n\n你好,世界。"}]
  }'

# Option B: Multimodal Image Translation API (OpenAI image_url format, base64 supported)
curl https://index-translate.bilibili.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "User-Agent: Index-Translate-Client/1.0" \
  -d '{
    "model": "Index-Translate-35B-A3B",
    "messages": [
      {
        "role": "user",
        "content": [
          {"type": "text", "text": "Translate the text in the image into Chinese."},
          {"type": "image_url", "image_url": {"url": "data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAQAAAC1HAwCAAAAC0lEQVR42mNk+A8AAQUBAScY42YAAAAASUVORK5CYII="}}
        ]
      }
    ]
  }'

# Option C: Modern OpenAI Responses API (compatible with client.responses.create / POST /v1/responses)
curl https://index-translate.bilibili.com/v1/responses \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Index-Translate-35B-A3B",
    "input": "请将以下文本翻译为英语,直接输出翻译结果,不要进行任何解释。\n\n你好,世界。"
  }'
Tip
✨ Multimodal Translation is Fully Live (Vision & Audio Speech)!
- 🖼️ Vision Multimodal (Image Translation): All sizes (2B / 9B / 35B) natively supported by our built-in vision encoder, zero OCR dependency, preserving layout and multimodal context. 👉 【Tutorial Guide】Multimodal Image Translation Complete Guide (API, Self-Hosting & Cases)
- 🎙️ Audio Multimodal (Speech Subtitles & Dubbing): Index-Echo supports end-to-end speech-to-subtitles (S2TT) and voice-cloned dubbing (S2ST). 👉 S2TT Subtitle Guide · S2ST Dubbing Guide
Tip
🌐 Bilingual Web Browsing? Immersive Translate is supported out-of-the-box (Windows / macOS / Linux)!
Browser extensions benefit from our zero-config local bridge proxy (Windows users can simply double-click run_proxy_windows.bat in the root folder).
👉 【Setup Guide】Immersive Translate Configuration Tutorial (Windows / macOS / Linux, with Screenshots & Troubleshooting)
Requires a CUDA GPU. You can serve models with either vLLM or SGLang:
git clone https://github.com/bilibili/Index-Translate.git
cd Index-Translate
pip install -r inference/llm/requirements.txt

# Option A: serve with vLLM (default port 8000)
./inference/llm/serve_vllm.sh translate-9b

# Option B: serve with SGLang (default port 30000, supports --mtp native speculative decoding, +20%-28% speedup)
./inference/llm/serve_sglang.sh translate-9b --mtp
⚡ MTP Speculative Decoding Acceleration: Index-Translate model checkpoints contain built-in Multi-Token Prediction (MTP) heads. On the 9B model, MTP speculative decoding achieves ~85% draft token acceptance and 1.22x ~ 1.28x decode acceleration (100+ tok/s)! See MTP Speculative Decoding & Acceleration Guide.
From the same repository directory in another terminal:
python inference/llm/translate.py \
  "你好,世界。今天天气不错,我们去公园散步吧。" \
  --target en --model IndexTeam/Index-Translate-2B
An output recorded with the released 2B model is:
Hello, world. The weather is nice today. Let's go for a walk in the park.
See captured cases, text inference, and prompt examples. The 4,096-token setting above is a short-text example; the serving presets are listed in the table below.
For audio, use the dedicated S2TT subtitle guide or S2ST dubbing guide.
Index-Translate deeply integrates instruction-following capabilities (instTrans). It supports both hard constraints (format preservation, strict terminology glossary enforcement) and soft constraints (tone & style, domain disambiguation) out of the box via translate.py and syllable_translate.py:
# Hard constraint 1: Strict terminology glossary enforcement (-g / --glossary)
python inference/llm/translate.py \
  "王平仲采用了更加昂贵的碳纤维材料。碳纤维的好处就是它抗裂缝。" \
  --target en -g "碳纤维:carbon fiber, 抗裂缝:crack resistance"

# Hard constraint 2: Untranslatable text & span lock (-g supports identity mapping e.g. "term:term")
python inference/llm/translate.py \
  '<span translate="no">我喜欢</span>花蓮的山海澎湖的潮汐' \
  --target en -g "我喜欢:我喜欢" -H "保留源文中的 HTML 格式标记不变"

# Hard constraint 3: Format & structure preservation (-H / --hard)
python inference/llm/translate.py \
  '{"user_id": 1024, "event": "purchase", "message": "您的订单已支付完成。"}' \
  --target en -H "保留源文中的 JSON 格式标记不变"

# Soft constraint 1: Tone and style adjustment (-S / --soft) + genre (-d / --genre)
python inference/llm/translate.py \
  "今天下午的会议临时取消了,改天我们再碰一下商量。" \
  --target en -d "商务邮件" -S "调整为严谨、正式、礼貌的商务公文风格"

# Soft constraint 2: Domain context and word-sense disambiguation (-S / --soft)
python inference/llm/translate.py \
  "The plant is operating at full capacity after the spring upgrade." \
  --target zh -d "工业制造" -S "语境为工业制造与重工厂房领域,准确消歧专有名词(如 plant 译为工厂而非植物)"

# Syllable control synergy: Index-Homura strictly respects syllable budgets while embedding glossaries
python inference/llm/syllable_translate.py \
  "我们今天去看电影吧" --syllables 7 --target en --glossary "电影:cinema"
instTrans Specification & Constraint Details:
- Canonical Prompt: Automatically formatted by the client into the instTrans benchmark structure (
【源文】+ numbered1. 【硬性要求】.../2. 【注意】...+ suffix instructions).- Hard Constraints: Structural formatting (JSON/CSV/code/placeholders), terminology glossaries, social elements, and syllable ordering. Binary gated ($g_{\mathrm{hard}}$); any single failure zeroes the instance score.
- Soft Constraints: Tone/style adaptation, contextual sense disambiguation, cross-sentence consistency, and LaTeX preservation. Evaluated on a graded scale ($q_{\mathrm{soft}}$).
- See the text inference guide and instruction cases for full examples.
This is the shared reference for the repository clients and the released Echo packages. Translate covers 2B / 9B / 35B-A3B (preview); the other families cover 2B / 9B. Decoding defaults are shared across sizes within each family.
Not set means the client inherits the backend/model configuration; — means the setting does not apply. Text-generation rows describe transcription/translation for Echo; speech generation has separate rows.
| Setting | Index-Translate | Index-Homura | Index-NativeLong | Echo S2TT | Echo S2ST |
|---|---|---|---|---|---|
| Entry point | translate.py |
syllable_translate.py |
doc_translate.py |
s2tt.py → package infer.py |
dub.py → package DubbingBridgeModel |
| Default checkpoint | 9B | 9B | 9B (Index-Nailong) |
2B | Local ./Index-Echo-S2ST-2B |
| Text decoding | Greedy | Sampling | Greedy | Greedy (do_sample=False) |
Greedy (do_sample=False) |
temperature |
0 |
0.3 |
0 |
0 |
0 (text) |
top_p |
Not set | Not set | 1 |
Not set | Not set (text) |
top_k |
Not set | Not set | -1 |
Not set | Not set (text) |
min_p |
Not set | Not set | 0 |
Not set | Not set (text) |
presence_penalty |
Not set | Not set | 0 |
— | — |
repetition_penalty |
Not set | Not set | 1 |
Not set | Not set (text) |
seed |
Not set | Not set | 42 |
Not set | 42 (speech) |
| Thinking | enable_thinking=False |
enable_thinking=False |
enable_thinking=False |
Empty <think> block prefilled |
Empty <think> block prefilled |
| Text output budget | max_tokens=1024 |
max_tokens=max(512, 3 * len(text)) |
max_tokens omitted; server selects the cap |
max_new_tokens=2000 per window |
max_new_tokens=1024 |
| Text stop conditions | Not set | Not set | stop_token_ids=[248044, 248046]; ignore_eos=False |
Tokenizer EOS / <|im_end|> |
Tokenizer EOS / <|im_end|> |
| Output streaming | No | No | stream=True |
Sequential window results | Speech stream=False |
serve_vllm.sh context (input + output) |
2B / 9B: 32768; no 35B preset |
32768 |
2B: 262144; 9B: 229376 |
— | — |
| Default language / constraint | Source auto, target en |
Target en; --syllables required |
zh-en |
zh-en |
--lang required; source inferred as zh/en |
| Audio window / history | — | — | — | --max-win 60 seconds; --ctx-k 5 prior windows |
Utterances ≤30 seconds recommended; chunk=False |
| Speech sampler | — | — | — | — | Fixed sampling=25; CosyVoice RAS defaults top_p=0.8, top_k=25 |
| Speech-token budget | — | — | — | — | Maximum min(1500, 20 * m); minimum 2 * m |
| Speech speed / sample rate | — | — | — | — | speed=1.0; 24000 Hz |
| Main overrides | --model, --instruction, --glossary, --temperature, --max-tokens |
--model, --syllables, --glossary, --temperature, --max-tokens |
--model, --direction, --max-tokens |
--size, --temperature, --max-new-tokens, --max-win, --ctx-k, --glossary |
--model-dir, --lang; lower-level API for budgets / seed |
- Text clients: default to
http://127.0.0.1:8000/v1with API keyEMPTY. Use--base-url/--api-keyorOPENAI_BASE_URL/OPENAI_API_KEY;--modeloverridesINDEX_MODELand the default checkpoint. Serve 35B-A3B manually and select it with--model IndexTeam/Index-Translate-35B-A3B-preview. - Budgets: Homura's
len(text)is the Python character count after trimming input. NativeLong's omittedmax_tokensleaves the output cap to the server; context capacity and server limits still apply. Pass a positive--max-tokensfor an explicit cap. Context includes the full prompt and generated output; override serving limits with--max-model-len. - Echo S2ST:
mis the aligned target-text token count.sampling=25is a fixed package-code argument, not a CLI option. The publicDubbingBridgeModel.dubwrapper exposes neitherseednor token budgets; use the lower-levelextract/synthAPI documented in the model card.chunk=Trueis not implemented. - Scope: these are usage defaults. The technical report's benchmark decoding and context settings are documented separately in Evaluation.
These examples are drawn from the official demo. Outputs below illustrate individual cases; full comparisons and task settings are available on the demo and in the report.
Prompt: Translate English text inside images into natural Chinese, deeply integrating visual layout and context without external OCR tools across all model scales (2B / 9B / 35B).
| Image Category | English Source Text in Image | Index-Translate (2B / 9B / 35B) Output (Chinese) | Key Highlight |
|---|---|---|---|
| Software Settings UI | "Enable hardware-accelerated GPU scheduling (requires restart)" | 启用硬件加速 GPU 计划(需要重启) | Accurate system terminology and clean segmentation |
| Technical Flowchart | "Client -> Load Balancer -> Worker Pool (Least-Conn Routing)" | 客户端 → 负载均衡器 → 工作节点池(最小连接数路由) | Preserves architectural concepts and flow directions |
| Physical Street Sign | "Pedestrian Crossing Ahead · Speed Limit 30 mph" | 前方行人过街通道 · 限速 30 英里/小时 | Robust against scene distortions and standard unit conversion |
All three sizes (2B / 9B / 35B) provide companion GGUF mmproj vision weights. Try it directly by uploading or pasting images on the Online Demo. See the Image Translation Guide for full details.

The S2ST panels compare the deployed 2B system, a pipeline, and SeamlessM4T-v2. This demo comparison is separate from the six-direction matched study in the report; SeamlessM4T-v2 does not clone the source voice.
| Speech Dubbing (S2ST) | Multilingual Subtitles (S2TT) |
|---|---|
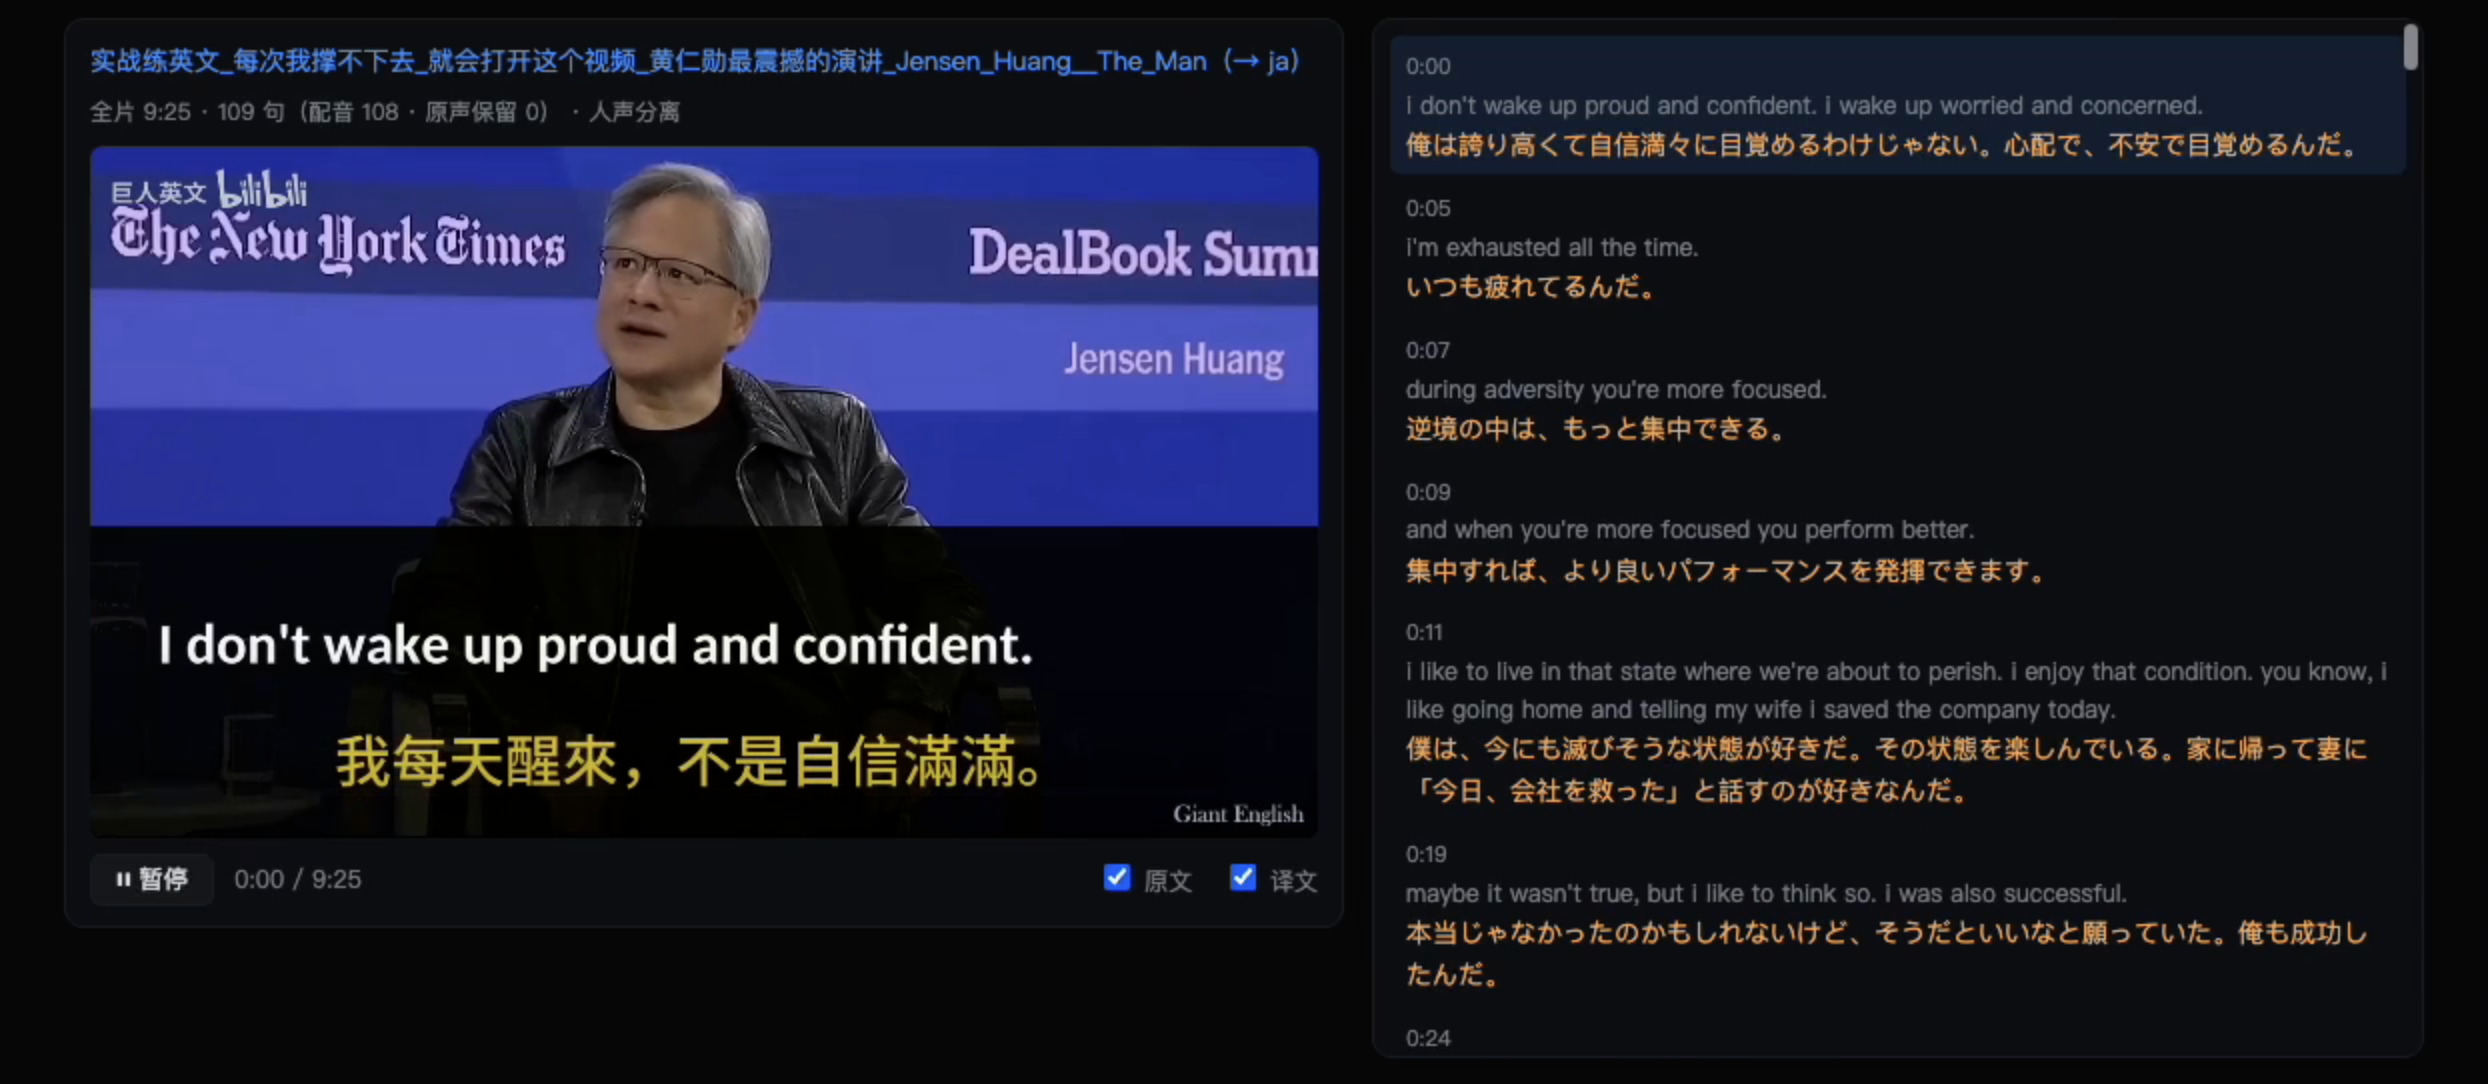 |
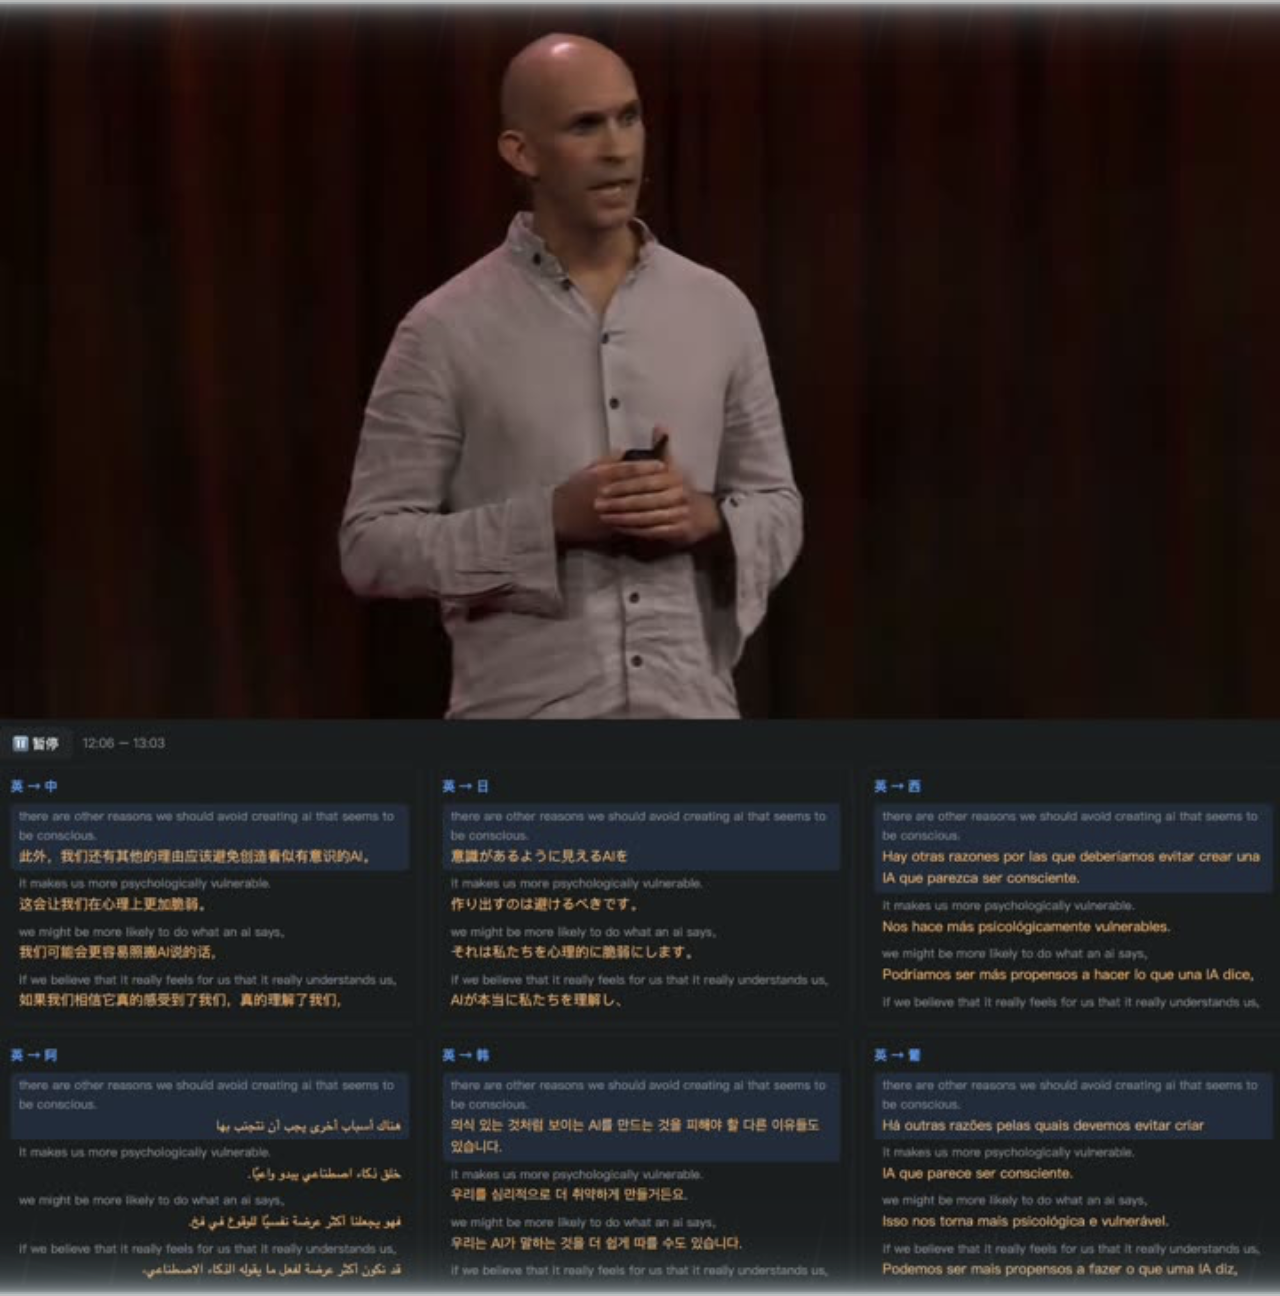 |
| English video with Japanese dubbing (voice cloned) | Same video with subtitles in multiple languages |
Click either preview to watch the video, or try Index-Echo online. The website demonstration and the packaged inference interfaces have different language coverage; the model table lists the released interfaces.
Task: translate this JSON into Korean, preserving its structure, stars, and the Chinese hashtag.
{"title": "⭐2月13日例行维护公告⭐", "content": "#热血航线大和登场#"}Index-Translate-9B:
{"title": "⭐2월 13일 정기 점검 공지⭐", "content": "#热血航线大和登场#"}The title is translated while the requested hashtag remains unchanged. Try text translation.
Source: 狒瘾犯了就去打 — in this gaming context, “狒瘾” refers to the urge to play Final Fantasy XIV.
| Model | English output |
|---|---|
| Index-Translate-9B | When the FFXIV itch hits, just go play. |
| Index-Translate-2B | Go play when my FFXIV addiction kicks in. |
| Hy-MT2-7B | If you get monkey addiction, go fight. |
Source: 生活两天,是一种什么体验. Index-Homura-9B produces different wording for three requested lengths:
| Target / observed syllables | English output |
|---|---|
| 10 / 10 | to live for two days. What would that be like? |
| 14 / 14 | What would it be like to live there for two days, I wonder? |
| 18 / 18 | What would it be like to live there for two days, trying to get by somehow? |
These three examples meet their targets; syllable control is approximate in general, and spoken duration also depends on delivery. Try Index-Homura.
In a roughly 32K-token fantasy document, “王妃” is a character's name. The following extracts compare native full-document translation with the same 9B model in a chunked workflow using neighboring context and an automatic glossary.
| Source position | Index-NativeLong-9B full document | Same 9B with chunking |
|---|---|---|
| 31.3% | Mentor Wang Fei | Instructor Wangfei |
| 56.6% | Wang Fei | the Dean |
| 84.8% | Wang Fei | The Queen Consort |
Positions are measured by source characters. The full-document output keeps the name at these locations; the demo also shows how an externally supplied glossary can repair the chunked result. Try Index-NativeLong.

The charts reproduce the updated demo comparison. *35B-A3B is the preview model. The instruction panels average instTrans and IFMTBench: Quality combines instTrans quality and IFMTBench XCOMET-XXL, while IFscore averages their instruction scores. Individual benchmark metrics remain separate in the tables below.
The following tables cover general text translation, low-resource translation, and low-resource instruction following. FLORES uses COMET-22; WMT26 uses a judge score. instTrans reports translation quality and instruction following separately. MEME measures translation quality for community and cultural expressions. Higher is better for every metric in the first table below; scales differ across columns.
| Model | FLORES ↑ | WMT26 ↑ | instTrans quality ↑ | instTrans IFscore ↑ | MEME ↑ |
|---|---|---|---|---|---|
| Index-Translate-35B-A3B (preview) | 0.8794 | 76.76 | 0.6901 | 0.8336 | 0.7405 |
| Index-Translate-9B | 0.8789 | 75.35 | 0.6771 | 0.8209 | 0.7387 |
| Index-Translate-2B | 0.8655 | 60.26 | 0.5391 | 0.7569 | 0.6443 |
| Hy-MT2-7B | 0.8747 | 60.51 | 0.5143 | 0.6079 | 0.5139 |
| Hy-MT2-30B-A3B | 0.8787 | 66.81 | 0.5725 | 0.6415 | 0.5812 |
| DeepSeek-V4.1-Flash | 0.8762 | 83.55 | 0.6068 | 0.6374 | 0.7424 |
| GPT-5.6-Sol | 0.8650 | 89.10 | 0.6902 | 0.7624 | 0.7194 |
| Gemini 3.5 Flash Lite | 0.8750 | 79.52 | 0.6068 | 0.6374 | 0.7034 |
FLORES_minor_pair evaluates general translation in low-resource languages; instTrans_minor reports translation quality and instruction following separately. Off-target is the percentage of outputs in a language other than the target language; lower is better. Higher is better for the other metrics. Bold marks the best value in each column of this table.
| Model | FLORES_minor_pair COMET-22 ↑ |
FLORES_minor_pair XCOMET-XXL ↑ |
FLORES_minor_pair off-target ↓ |
instTrans_minor Quality ↑ |
instTrans_minor IFscore ↑ |
instTrans_minor off-target ↓ |
|---|---|---|---|---|---|---|
| Index-Translate-35B-A3B (preview) | 0.8168 | 0.7164 | 2.4% | 0.5151 | 0.7715 | 4.05% |
| Index-Translate-9B | 0.7992 | 0.6805 | 4.0% | 0.5222 | 0.7725 | 3.47% |
| Index-Translate-2B | 0.7377 | 0.4817 | 4.2% | 0.3050 | 0.6586 | 3.97% |
| Hy-MT2-7B | 0.4626 | 0.3334 | 35.7% | 0.1121 | 0.2405 | 45.40% |
| Hy-MT2-30B-A3B | 0.6746 | 0.5359 | 14.5% | 0.2246 | 0.4449 | 15.47% |
| DeepSeek-V4.1-Flash | 0.8333 | 0.7297 | 1.3% | 0.4793 | 0.5854 | 5.73% |
| GPT-5.6-Sol | 0.7669 | 0.6918 | 10.4% | 0.5757 | 0.6866 | 7.73% |
| Gemini 3.5 Flash Lite | 0.8122 | 0.6995 | 3.3% | 0.3927 | 0.5584 | 12.18% |
Among the three Index-Translate models, 35B-A3B (preview) has the highest FLORES_minor_pair COMET-22 and XCOMET-XXL scores (0.8168 / 0.7164), with a 2.4% off-target rate. On instTrans_minor, Index-Translate-9B achieves the highest IFscore (0.7725) and lowest off-target rate (3.47%) among all compared models; its quality score is 0.5222.
Full tables retain all comparison models, low-resource metrics, WMT24++, IFMTBench, domain averages, general capabilities, speech, SandGlass, and long-document results. Detailed settings and analysis are in the technical report.

SandGlass overall score and length adherence from the demo; the overall score differs from the separate translation-quality metric in the detailed tables.

GuoFeng and BWB Track A3 at 64K Chinese-side tokens.
For the specialized models, Index-Homura-9B reaches 81.92% within 10% of the target syllable count on SandGlass. Index-NativeLong-9B scores 0.7891 / 0.7683 / 0.8848 on GuoFeng / BWB / Books. The full tables include translation-quality tradeoffs and evaluation notes.
Find the datasets and metadata in the 🤗 Index-Translate Benchmarks collection. Evaluation scripts, a pinned data downloader and run instructions are available in benchmarks/.
| Benchmark | Public release | Dataset | Evaluation code and guide |
|---|---|---|---|
| instTrans | 3,000 translation instruction tasks; 10 constraint types | 🤗 InstTrans-Bench | insttrans |
| MEME | 3,638 Chinese-to-English cases; 703 terms and 857 senses | 🤗 Meme-Translation-Bench | meme |
| SandGlass | 3,600 cases: 300 subtitles × 4 target languages × 3 length budgets | 🤗 Sandglass-Bench | sandglass |
| NAtIveLong | Metadata for 84 BWB and 84 GuoFeng long-document cases, evaluation code and acquisition instructions | 🤗 NAtIveLong | nativelong |
NAtIveLong includes no source novels or reference translations: obtain official BWB data separately; GuoFeng provides a local reconstruction tool. The instTrans release does not include the 2,793 low-resource extension tasks in the evaluation tables. Original prompts are preserved; each directory's RELEASE_REVIEW.md records review changes and validation limits. Historical scores have not been rerun. Each benchmark has its own licensing terms; the repository's root license does not replace them.
See the full evaluation settings and IFMTBench preprocessing for other results.
- Immersive Translate Guide: step-by-step tutorial with screenshots for Windows (one-click
.batscript provided) / macOS / Linux to use the free public 35B API or local models with Immersive Translate. - Multimodal Image Translation Guide: comprehensive guide for native vision encoder usage, local deployment, and OpenAI API formatting.
- Multimodal Video Dubbing Pipeline: complete toolchain for video audio extraction, vocal separation, speech segmentation, translation, dubbing, and timeline alignment.
- Native Browser extension: lightweight built-in webpage translator supporting Chrome, Edge, and Firefox.
Open-source projects and applications built with Index-Translate:
- simul-subtitle (by @KorenKrita): Real-time on-device subtitle translation for Android. Recognizes Japanese/English speech, translates into 22 languages powered by Index-Translate, and renders floating live subtitles over any app.
Join the QQ group (960123527) for discussion and feedback. You can also scan the QR code below to join.
Browse all three papers in the 🤗 Hugging Face Papers collection.
- Index-Translate: A Multilingual Translation Model Family — Text, Speech, Controlled Dubbing, and Long-Document Translation · 🤗 HF Papers
- HOMURA: Taming the Sand-Glass for Time-Constrained LLM Translation via Reinforcement Learning · 🤗 HF Papers
- RIVAL: Reinforcement Learning with Iterative and Adversarial Optimization for Machine Translation · 🤗 HF Papers
If you use this model family or its related methods, please cite the relevant papers:
@techreport{indextranslate2026,
  author={Tianjiao Li and Mengran Yu and Chenyu Shi and Lusheng Zhang and
          Qisi Chen and Yanshan Zhou and Ji Qi and Jingying Liu and
          Yuang Feng and Ziang Cui and Tianxing Yan},
  title={Index-Translate: A Multilingual Translation Model Family --- Text, Speech, Controlled Dubbing, and Long-Document Translation},
  institution={Index LLM Team},
  year={2026},
  month={September},
  eprint={2609.40181},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2609.40181}
}

@misc{homura2026,
  author={Ziang Cui and Mengran Yu and Chenyu Shi and Yingxuan Shi and Tianjiao Li},
  title={HOMURA: Taming the Sand-Glass for Time-Constrained LLM Translation via Reinforcement Learning},
  year={2026},
  eprint={2601.10187},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2601.10187}
}

@misc{rival2025,
  author={Tianjiao Li and Mengran Yu and Chenyu Shi and Yanjun Zhao and
          Xiaojing Liu and Qiang Zhang and Qi Zhang and Xuanjing Huang and Jiayin Wang},
  title={RIVAL: Reinforcement Learning with Iterative and Adversarial Optimization for Machine Translation},
  year={2025},
  eprint={2506.05070},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2506.05070}
}Apache-2.0. Questions and feedback are welcome through GitHub Issues.